Your AI workforce is already on the payroll, from coding assistants to autonomous agents. Revenium attributes every dollar it spends to the team, feature, and customer behind it, and catches runaway costs before the bill arrives.
Agents spend autonomously, across every provider, and the tools you have weren’t built to catch it.
One mis-configured key burned $90K in a week. Costs pile up across providers and agents with no single view, and the bill arrives before the alert does.

You can see one big number, but not which team, customer, or agent spent it. Inference got 280× cheaper. Spend exploded anyway, and no one can say what drove the bill.

“You spent six figures on AI. What did we get?” 78% of leaders feel board pressure to prove AI value and say old metrics can’t. 65% say realizing ROI is proving difficult.

The roster for your AI workforce.
Every model call, agent turn, and tool call, attributed to the team, customer, feature, and agent behind it. The itemized truth in real time, not just a provider bill.

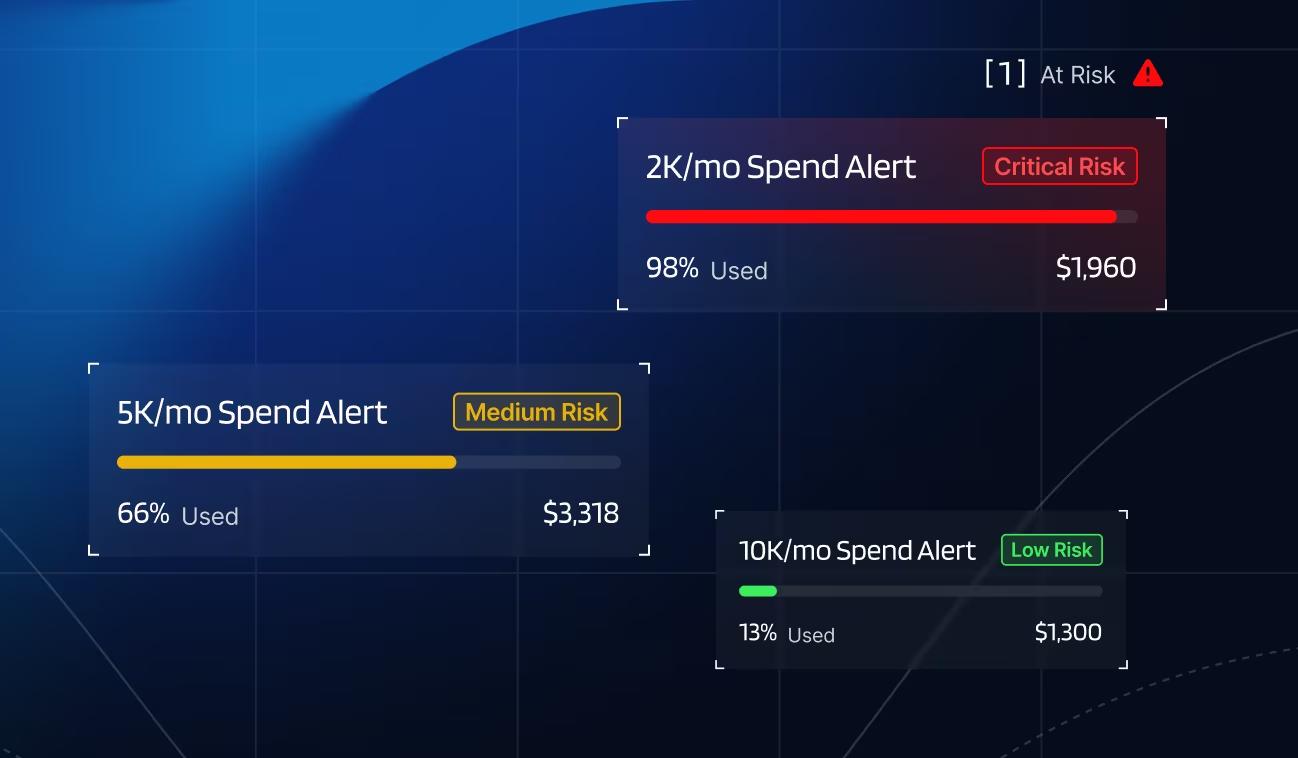
A budget for every agent, set before it spends.
Cut the waste already on your bill: old-model usage, retry loops, dormant keys, oversized models. Then set guardrails that start in shadow mode and alert before they're enforced.
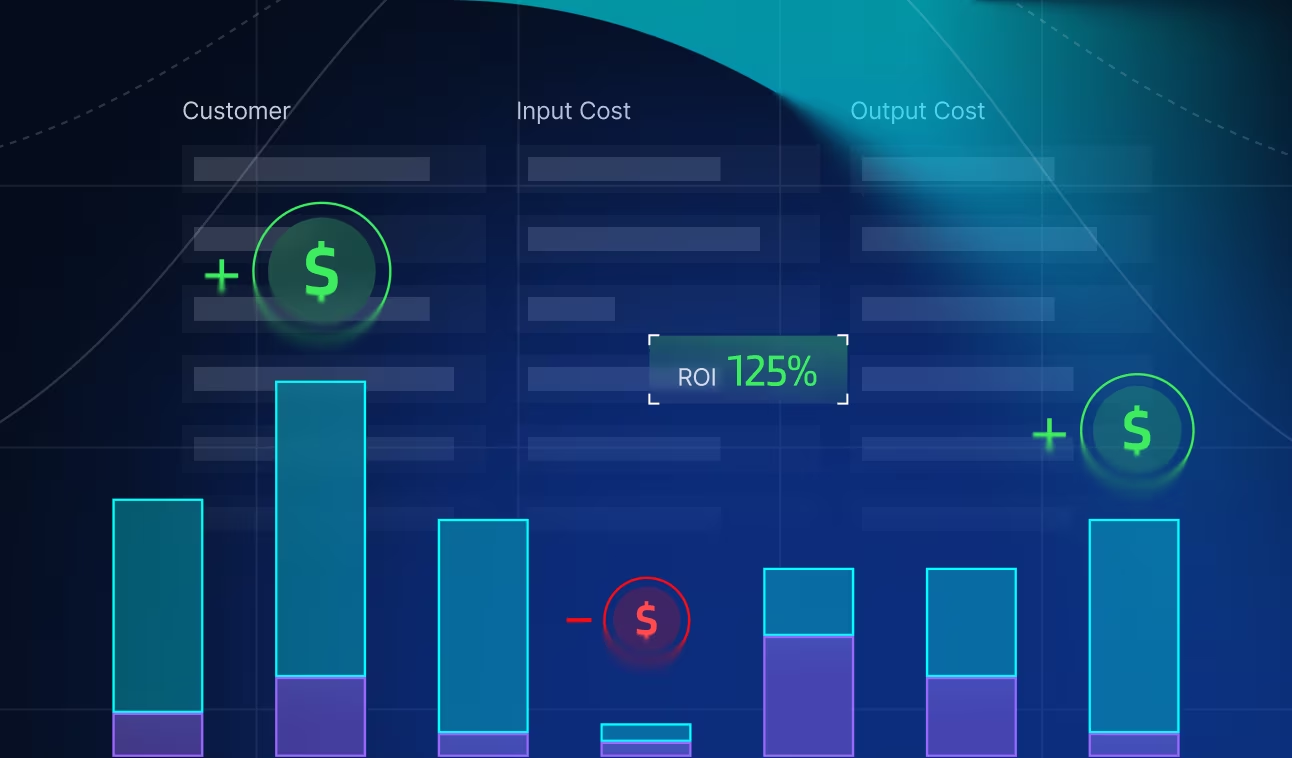
A performance review for every workflow.
Connect cost to outcome: TCO, COGS, and ROI per workflow, including the tool calls and human rescue time behind each one. Spot waste and forecast spend before it compounds.


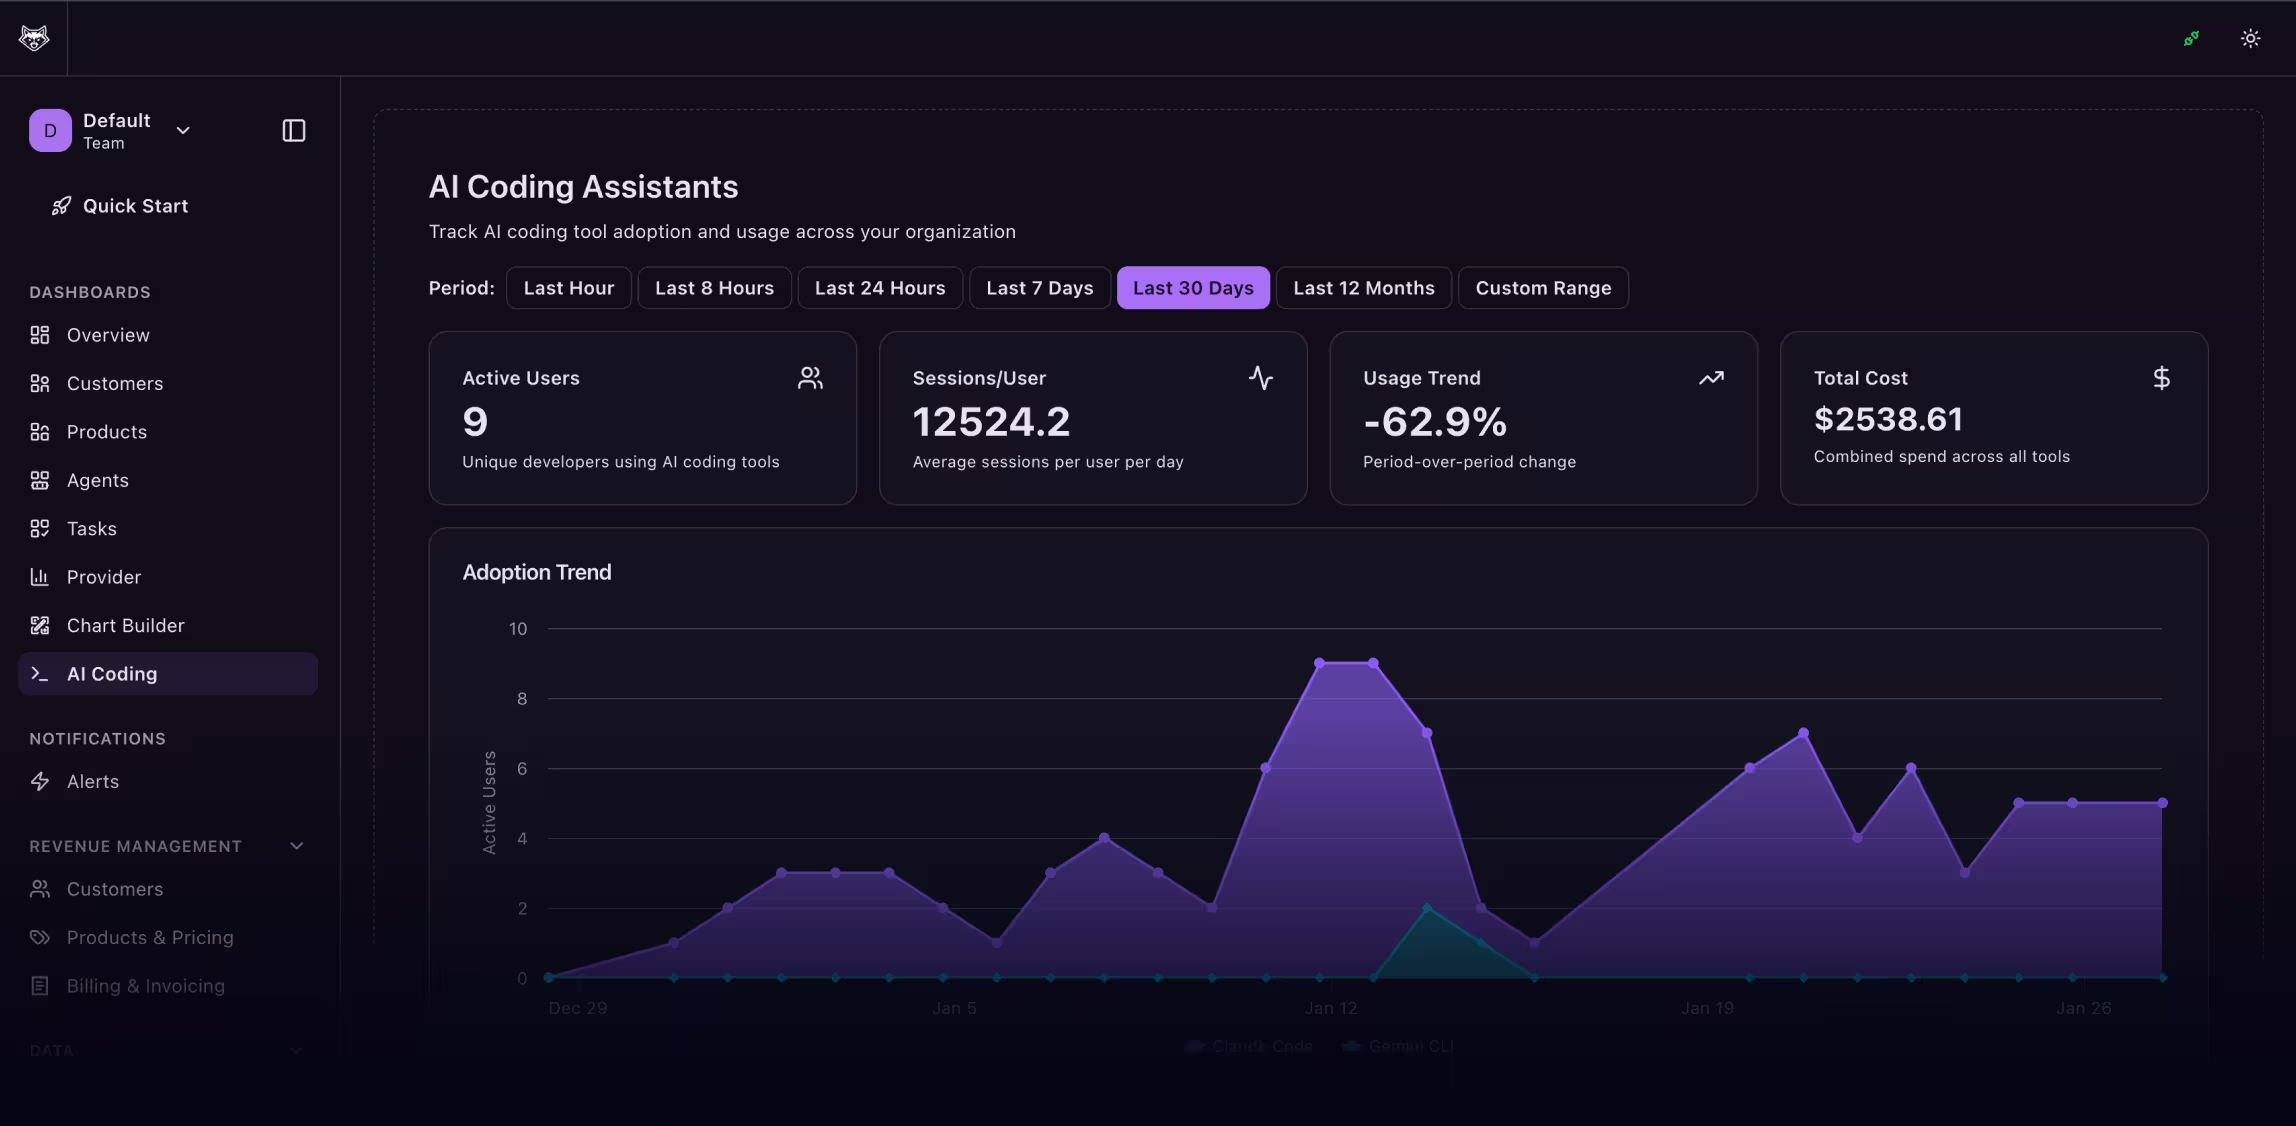
Start with the first hires of your AI workforce, your coding assistants. See cost per engineer, per PR, and per session in about 15 minutes. Then catch the $10K runaway before it happens.
Attribute AI spend for board-level accountability. One defensible number by team, customer, and agent, that turns unpredictable AI variance into a line item you can manage.


Model unit economics before you scale. Exact COGS per feature and customer segment, so you price AI products on what they actually cost.
Connect your LLM providers and see attribution with one copy-paste